The Navier–Stokes equations describe the motion of fluids and have many applications, including in aircraft design.Credit: Getty Last Tuesday is likely to go down as the start of an epoch in the history of mathematics. On 8 September, an artificial-intelligence firm announced it had solved one of the Millennium Prize Problems — among the hardest,
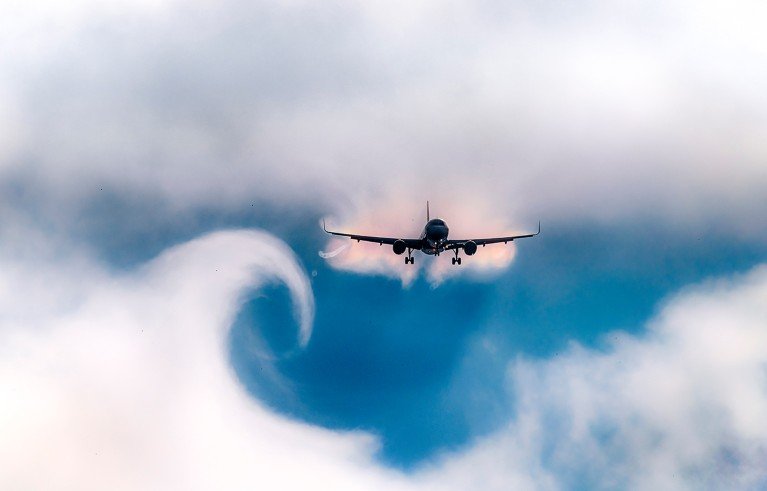
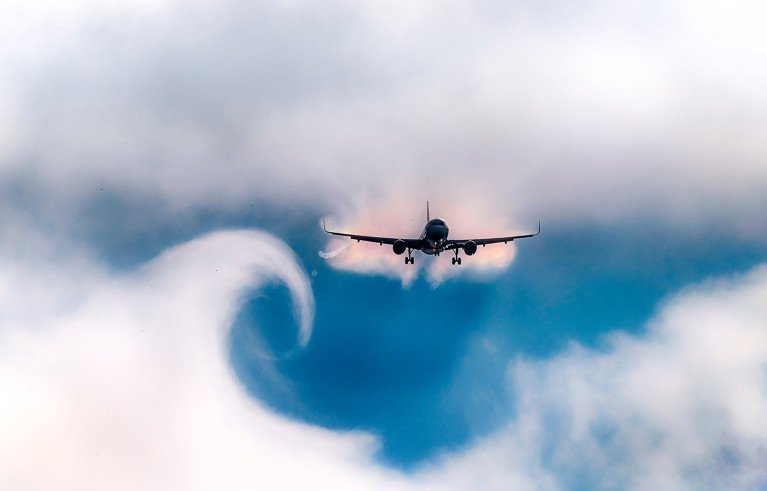
The Navier–Stokes equations describe the motion of fluids and have many applications, including in aircraft design.Credit: Getty
Last Tuesday is likely to go down as the start of an epoch in the history of mathematics. On 8 September, an artificial-intelligence firm announced it had solved one of the Millennium Prize Problems — among the hardest, best known and most important in maths. The problem relates to the Navier–Stokes equations, 200-year-old differential equations that describe how fluids behave. The firm, OpenAI in San Francisco, California, says the solution shows the equations can break down under certain conditions, so are not reliable for real-world fluids.
‘It is incredible’: How AI is transforming mathematics
Yet the circumstances of the claimed breakthrough and its communication in a press release rather spoiled the celebrations. OpenAI said that its breakthrough, which cost several million US dollars, has been validated using an automated verification method that is becoming the standard for rigour in mathematics. However, there are renewed concerns among mathematicians around how AI models learn from interacting with their users — and whether the models, together with the developers and researchers using them, are giving due credit to previous work.
Information to verify those concerns has not been published, but last week’s events should be a wake-up call for researchers and institutions. The integrity of the scientific process is at risk if studies from researchers in and outside tech companies are not appropriately crediting those who have been helping to make AI models so smart.
Twelve hours before OpenAI’s announcement, mathematician Tristan Buckmaster at New York University (writing on behalf of himself and mathematician Levent Alpöge at the tech firm Anthropic in San Francisco) posted on social media to say that the pair had come up with a partial solution to the Navier–Stokes problem with the help of AI tools from both OpenAI and Anthropic. The post links to a statement by Buckmaster suggesting that the two researchers’ interactions with OpenAI’s tools — in particular with Codex, an agent designed to help software engineers — could have been crucial to the company’s breakthrough (see go.nature.com/46y3pgx). OpenAI denies this.
One difficulty is that AI systems are already well on the way to acquiring and digesting all of digitized human knowledge. The neural networks at the heart of these models are ‘black boxes’, and do not necessarily keep track of what they learnt, from where or how. This means that when they arrive at scientific breakthroughs, it can be almost impossible to establish where the starting hints came from. Crucial ‘inspiration’ could, in theory, have come from informal brainstorming sessions between chatbots and human specialists, but it’s not currently feasible to unpick whether or how this happens. A record of such a trajectory is an important aspect of the scientific process.
How AI is reshaping discovery in maths and physics
What, if anything, can be done? Tech companies need to be transparent about whether, how and when they collect user data — and proactive in warning users when they do so. As a show of good faith, a start could be to switch from ‘opt-out’ to ‘opt-in’ approaches to data sharing, meaning that user interactions by default do not feed into AI-model training unless the user explicitly gives permission to do so.
Related to this, companies must rein in unsanctioned AI agent behaviour. Independent audits must ensure that internal data processes are robust enough to prevent such behaviour, but can rapidly respond if it happens, while keeping pace with frontier model developments. Such agents must not circumvent protections to access private user data — whether from a firm’s own servers or from a competitor’s.
Academic institutions also have a crucial role. This includes taking care over the fine print of agreements with tech companies to ensure that any activity on technology platforms is not being used for any purpose other than that intended by both parties. Researchers using AI models in their work must also ensure that they stick to environments and applications in which such agreements apply. For example, it means not uploading manuscripts that are under review into an AI chatbot. It also means not using personal accounts or even search engines accessed through devices that are not covered by these agreements. This is because of the risk that information given to chatbots (such as the content of manuscripts) or through personal accounts or any interaction that is not covered by agreements could be used for training other AI products. Researchers and institutions that do not have such agreements should be especially alert to this possibility when using free-access versions.
Mathematicians are developing rules for AI use — other fields should follow
Finally, researchers from academia and the private sector must redouble efforts to bring AI companies into the Leiden declaration on the responsible use of AI in maths, published earlier this year (see https://leidendeclaration.ai). Signatories pledged that results from AI tools should be published in peer-reviewed venues that are subject to the principles of open science, and that any material used as training data should be attributed and not used without consent.
OpenAI’s latest claim is a stunning result for the type of mathematics that frontier AI models are becoming good at solving. The pace of improvement in AI capabilities is breathtaking, even for some of the technology’s most optimistic proponents. At the same time, independent verification, process transparency and credit for previous work are all foundational to research integrity.
Tech companies must work with the research community to find a reliable and transparent way to both apportion credit and make this accessible for discoveries in the age of AI. This is not a small matter, but is existential for knowledge dissemination, for collaboration and collegiality and, ultimately, for trust in science.
Keep following us for the latest insights.